Newer AI models missed more payment fraud in Coinbase’s benchmark
Coinbase announced that newer iterations of three prominent AI model families failed to catch as many fraudulent payments during a historical payment-screening benchmark for its Onramp service, challenging the assumption that upgrading automatically improves security.

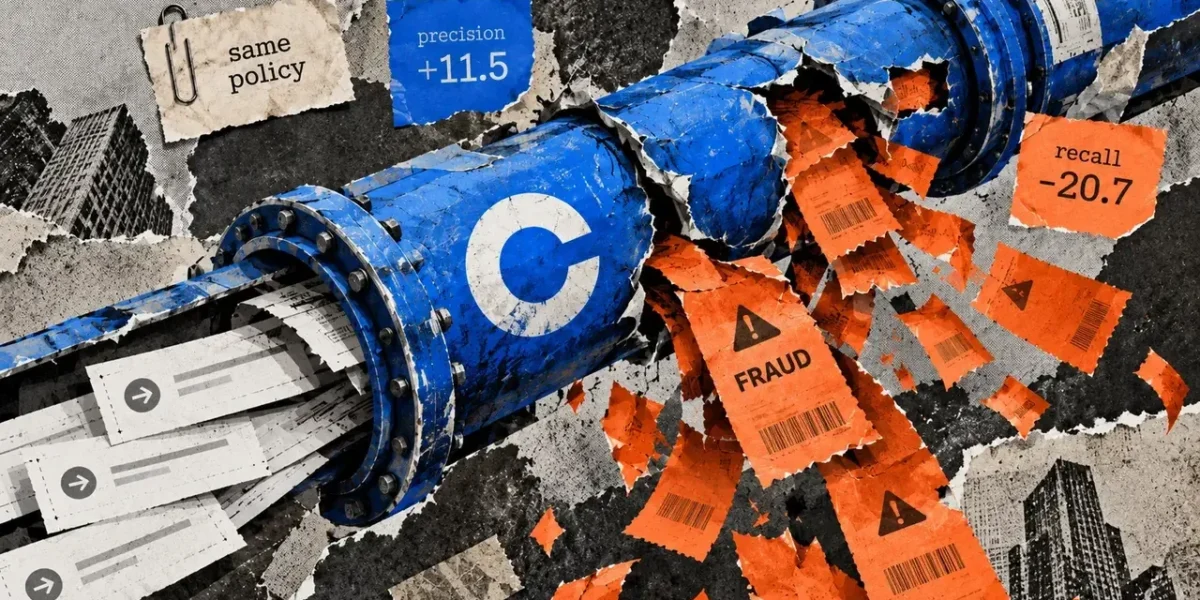
On Oct. 7, Coinbase announced that recent iterations of three prominent AI model families failed to catch as many fraudulent payments—and missed a larger portion of total fraud value—during a historical payment-screening benchmark for its Onramp service. This occurred despite the decision policy remaining completely unchanged. These results challenge the common belief that simply upgrading to a newer model automatically enhances an existing payment-screening tool.
To conduct the evaluation, the firm replayed 16,140 transactions involving 7,293 users, which included 813 verified fraudulent transactions. This test group spanned the nine-week period right before the deployment of its risk agent, keeping all matured fraud incidents while taking a sample of legitimate user traffic.
Each tested model analyzed recent transaction patterns using strict guidelines and an identical framework for translating risk classifications into final decisions. By doing this, the setup isolated the behavior of the decision model itself rather than evaluating entirely overhauled screening mechanisms.
Results from a fixed historical replay
The company contrasted Opus 4.5 against Opus 5, Sonnet 4.6 against Sonnet 5, and GPT-5.4 against GPT-5.6 (sol). Every single newer version demonstrated reduced recall, a lower combined precision-and-recall metric known as the F1 score, and diminished dollar-weighted recall. Recall tracks the proportion of fraud incidents successfully intercepted by a model, whereas dollar-weighted recall tracks the percentage of overall fraudulent monetary value captured.
For Sonnet, recall dropped by 22.2 percentage points alongside a 22.9-point decrease in dollar-weighted recall. Meanwhile, Opus saw its recall decline by 0.8 points. Both updated models also exhibited reduced precision, indicating that a smaller percentage of the transactions they flagged as fraudulent were genuinely malicious.
The GPT evaluation demonstrated why relying on a single improving metric can prove misleading. While its precision climbed by 11.5 percentage points, its recall plummeted by 20.7 points and dollar-weighted recall dropped by 21.8 points. Consequently, although its fraud warnings were more precise, a greater number of fraudulent transactions and higher monetary values managed to bypass detection during the replay.
The historical replay does not quantify actual customer financial losses resulting from the implementation of those particular versions. Furthermore, Coinbase noted it could spot these performance regressions without identifying their underlying root causes.
An earlier online experiment by Coinbase analyzed the impact of pairing selective large language model (LLM) reviews with traditional models and rules. That agent-supported configuration achieved a 30% reduction in fraudulent transactions and cut fraud value by 22%, though it did not evaluate newer model variations.
Addressing the constraints of the research, the SR-Fraud investigators pointed out that the proprietary dataset cannot be shared publicly, which prevents independent replication and broader generalization. Their associated payment-fraud paper debuted on Sept. 23 and underwent revisions on Sept. 30, preceding the October blog publications.
A separate case for a custom model
In an Oct. 8 disclosure, Coinbase revealed that a post-trained Qwen3.5-9B model outperformed Opus 4.5 across four distinct fraud-detection benchmarks. Its F1 score jumped by 9.6 percentage points, and dollar-weighted recall surged by 35.4 points. The business fine-tuned this model leveraging historical fraud data alongside deterministic rewards that balanced fraudulent and legitimate transaction examples.
In separate production tests, the median end-to-end latency for LLM requests clocked in at 0.683 seconds compared to 1.515 seconds for Opus 4.5, marking a 55% relative speed improvement. These performance gains in inference speed and benchmark detection stemmed from entirely separate assessments.
When considering upgrades, payment platforms must determine whether a candidate model actually enhances fraud coverage under their specific decision architecture. Coinbase advises testing that exact framework initially, evaluating modifications to prompts or thresholds independently, and factoring in latency, system reliability, and operational costs alongside raw detection performance.
Frequently Asked Questions
01Did newer AI models perform better at detecting payment fraud in Coinbase’s tests?
No. Newer versions of three major AI model families actually caught fewer fraudulent transactions and missed a larger share of fraud value compared to older versions when tested under a fixed historical replay.
02What metrics did Coinbase use to evaluate the AI models?
The company evaluated models based on recall (share of fraud cases caught), dollar-weighted recall (share of total fraud value caught), precision, and the combined F1 score.
03What is a custom-trained model alternative mentioned in the report?
Coinbase reported that a post-trained Qwen3.5-9B model—fine-tuned using historical fraud data and deterministic rewards—outperformed Opus 4.5 across four fraud-detection metrics while offering significantly faster request latency.